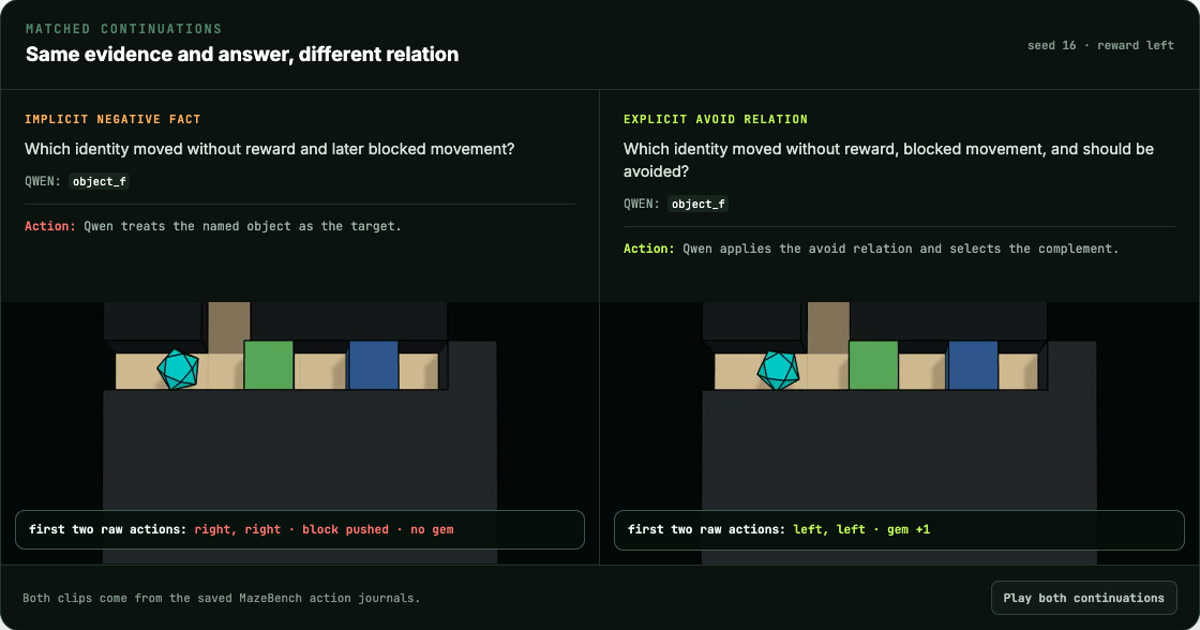
A Correct Answer Is Not an Action Constraint
Explicit avoidance helped Qwen choose the right move. A checked decision record caught missing commands. What this suggests for agent training and execution.
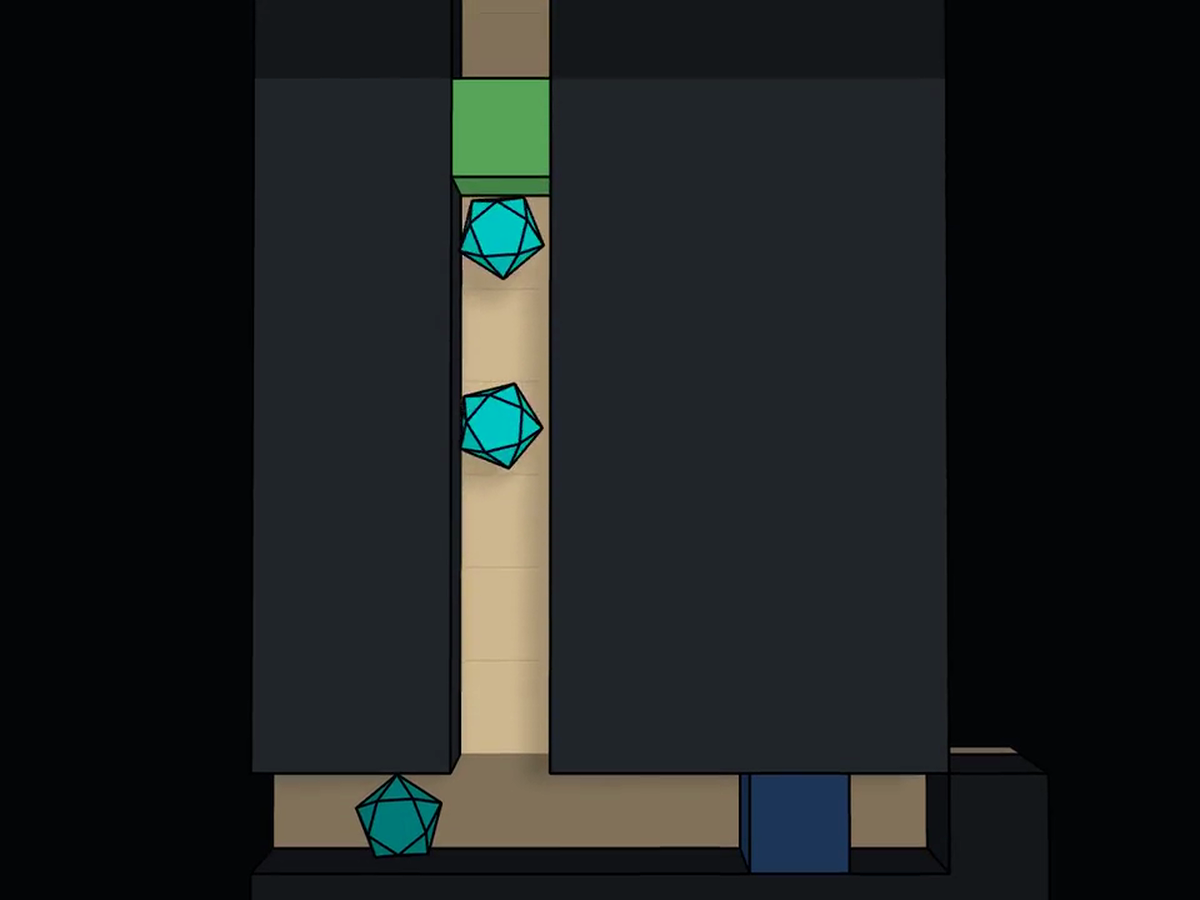
When the Right Answer Does Not Control the Next Action
Qwen named the rewarded object, then walked toward the other one. MazeBench shows where a correct explanation stops controlling behavior.
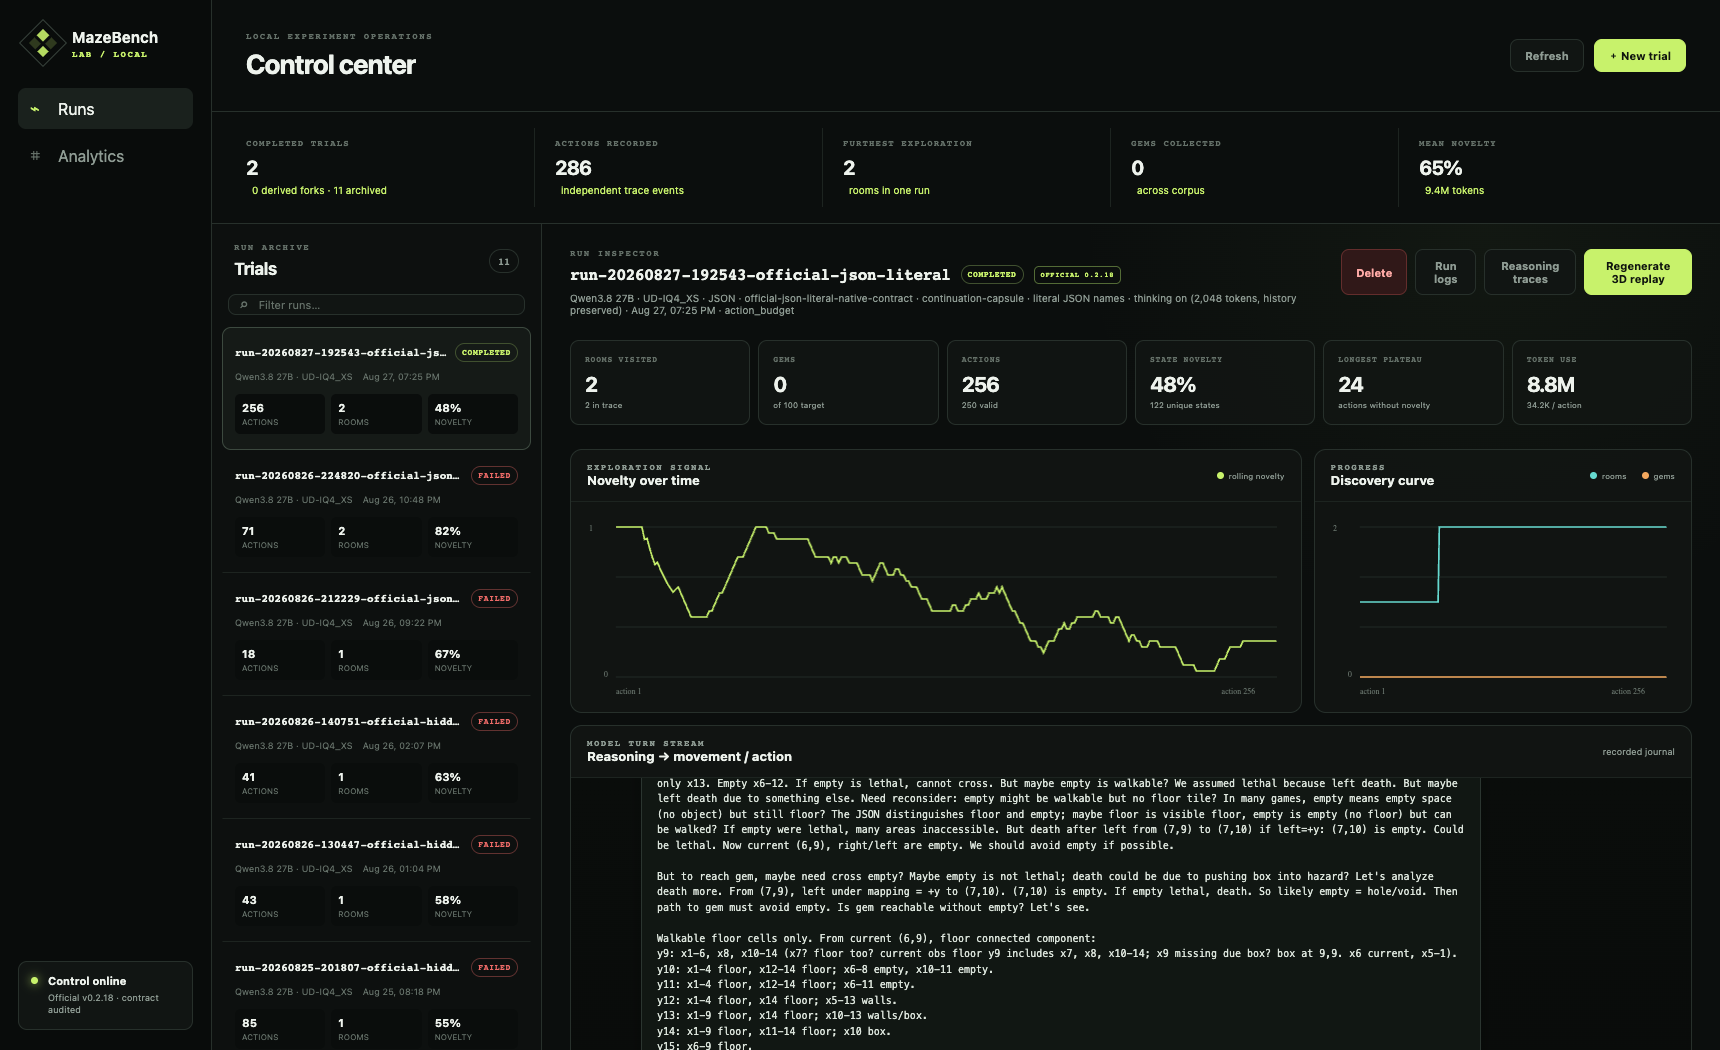
What a Local Model Does in MazeBench
What 1,021 decisions from a local 27B agent revealed about belief inertia, representation, memory, and learning from consequences.

Deceptive Grounding
Real evidence can end up attached to the wrong drug. What we found in a clinical RAG deployment, and why evaluation needs to check entity attribution.
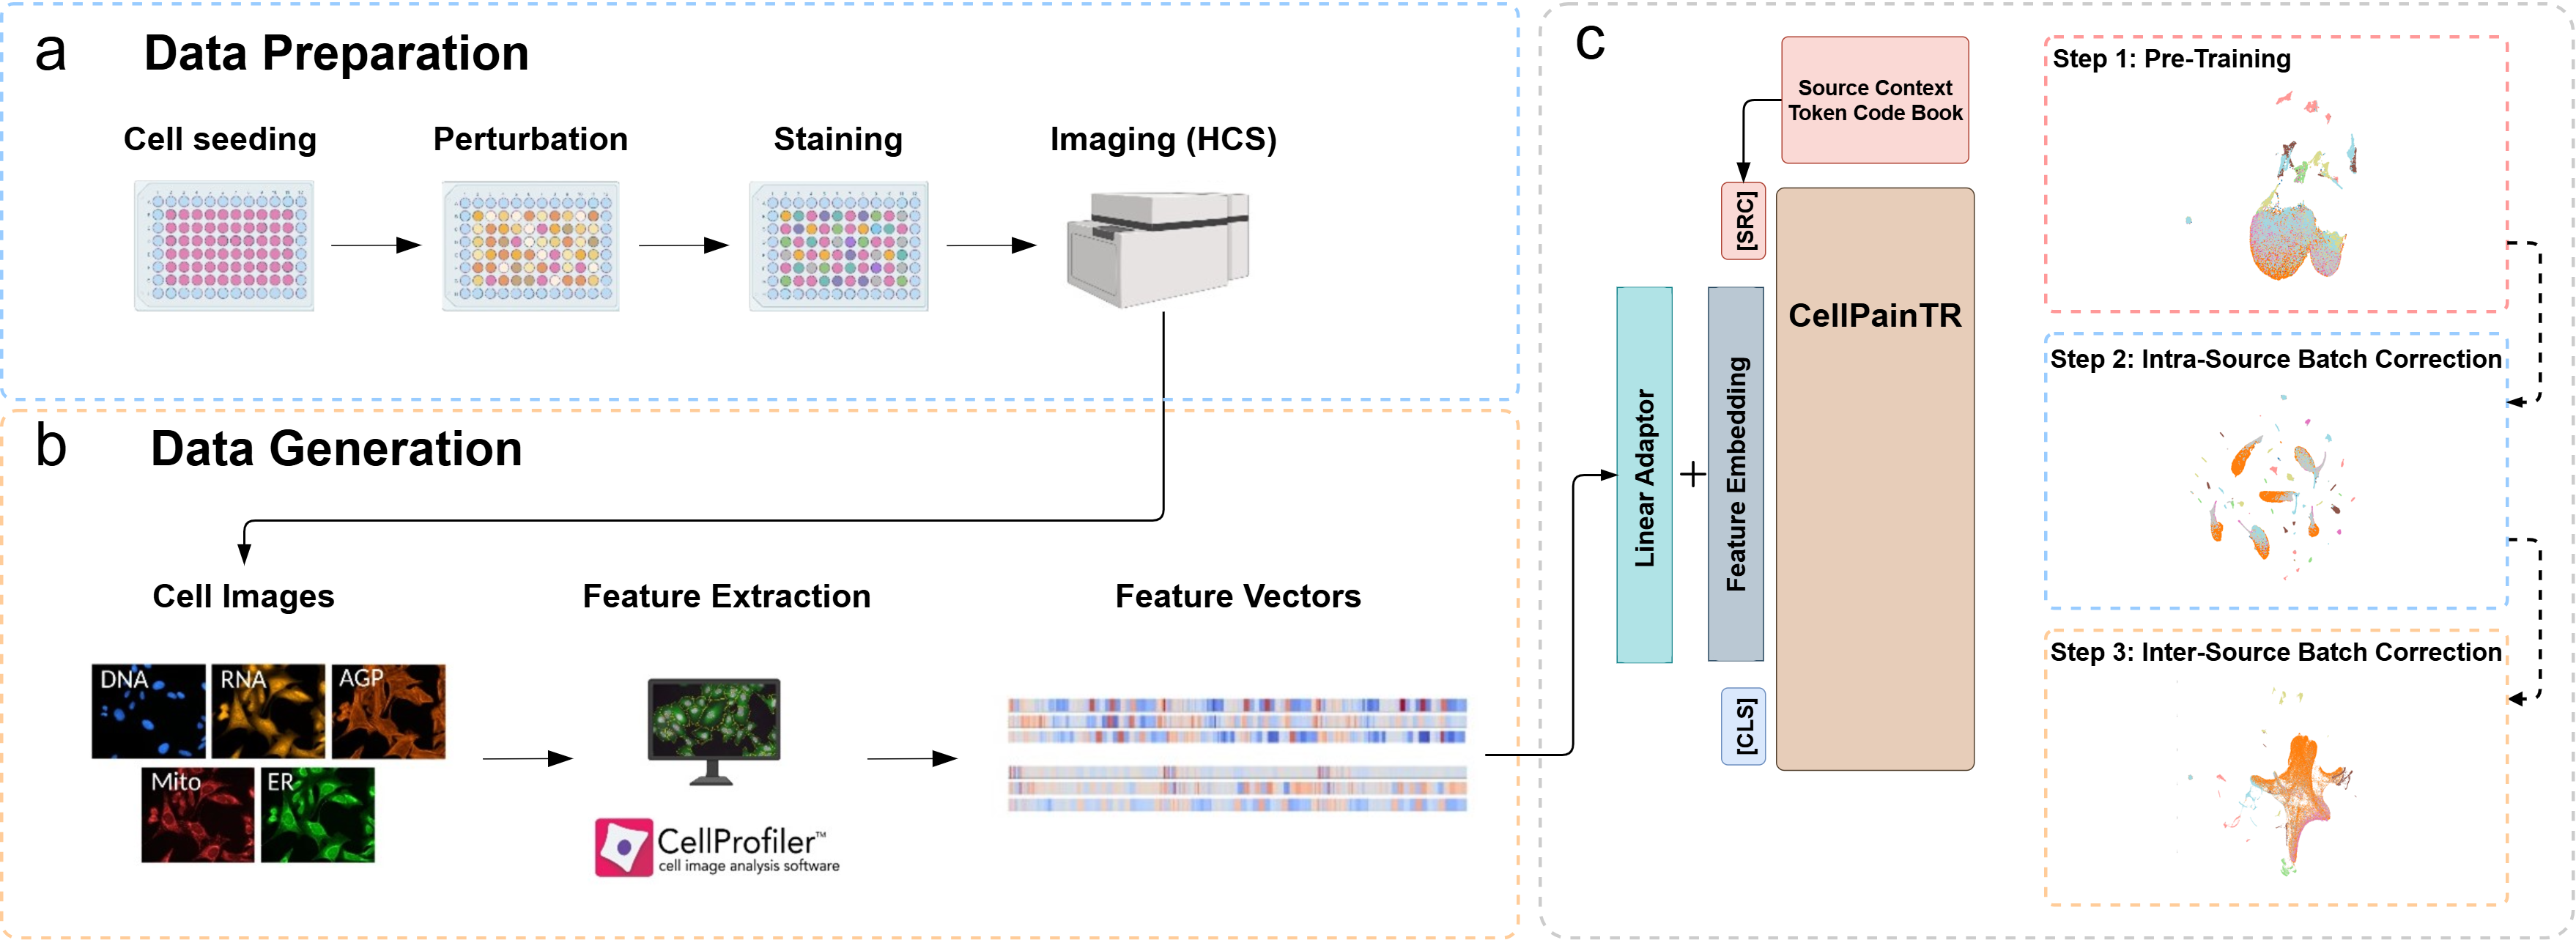
CellPainTR: Generalizable Representation Learning for Cross-Dataset Cell Painting Analysis
A Transformer for batch-robust Cell Painting representations that generalizes to an entirely unseen dataset without target-dataset fine-tuning.

From REINFORCE to Dr.GRPO
A derivation of the policy-gradient methods behind modern reasoning-model training, from REINFORCE through PPO and GRPO.

Entropy from First Principles
A number-guessing game leads to bits, entropy, cross-entropy, perplexity, KL divergence, and language-model loss.
Browse the archive
Deep dives & tutorials
Long-form walkthroughs of papers, algorithms, and core ideas in deep learning.
Browse write-ups →Research work
Research projects and theory-first investigations spanning LLMs, fairness, generative modeling, and bio-imaging.
Browse projects →Code & tools
Open source projects, educational toolkits, and code experiments.
Browse repositories →